Databricks certification practice

CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK-3-5-QUESTIONS Practice Questions

Try 10 free CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK-3-5-QUESTIONS exam-style questions for Databricks CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK-3-5-QUESTIONS certification exam. Check each answer and review the explanation and source references.

Exam code
CERTIFIED-ASSOCIATE-DEVELOPER-FOR-APACHE-SPARK-3-5-QUESTIONS
Provider
Databricks
Free questions
10
Full set
135 questions
Last update check
You have: DataFrame A: 128 GB of transactions DataFrame B: 1 GB user lookup table Which strategy is correct for broadcasting?
Answer options
A Spark DataFrame df is cached using the MEMORY_AND_DISK storage level, but the DataFrame is too large to fit entirely in memory. What is the likely behavior when Spark runs out of memory to store the DataFrame?
Answer options

44 of 55. A data engineer is working on a real-time analytics pipeline using Spark Structured Streaming. They want the system to process incoming data in micro-batches at a fixed interval of 5 seconds. Which code snippet fulfills this requirement?
Answer options
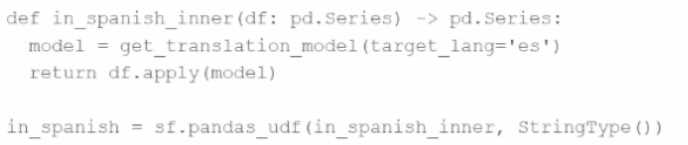
An MLOps engineer is building a Pandas UDF that applies a language model that translates English strings into Spanish. The initial code is loading the model on every call to the UDF, which is hurting the performance of the data pipeline. The initial code is: Databricks DATABRICKS CERTIFIED ASSOCIATE DEVELOPER FOR APACHE SPARK 3 question def in_spanish_inner(df: pd.Series) -> pd.Series: model = get_translation_model(target_lang='es') return df.apply(model) in_spanish = sf.pandas_udf(in_spanish_inner, StringType()) How can the MLOps engineer change this code to reduce how many times the language model is loaded?
Answer options
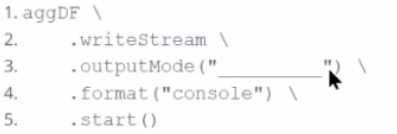
In the code block below, aggDF contains aggregations on a streaming DataFrame: Databricks DATABRICKS CERTIFIED ASSOCIATE DEVELOPER FOR APACHE SPARK 3 question Which output mode at line 3 ensures that the entire result table is written to the console during each trigger execution?
Answer options
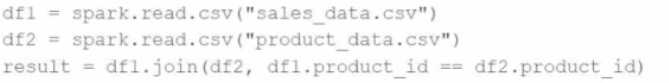
A data engineer writes the following code to join two DataFrames df1 and df2: df1 = spark.read.csv("sales_data.csv") # ~10 GB df2 = spark.read.csv("product_data.csv") # ~8 MB result = df1.join(df2, df1.product_id == df2.product_id) Databricks DATABRICKS CERTIFIED ASSOCIATE DEVELOPER FOR APACHE SPARK 3 question Which join strategy will Spark use?
Answer options
A developer wants to test Spark Connect with an existing Spark application. What are the two alternative ways the developer can start a local Spark Connect server without changing their existing application code? (Choose 2 answers)
Answer options
A data engineer is running a Spark job to process a dataset of 1 TB stored in distributed storage. The cluster has 10 nodes, each with 16 CPUs. Spark UI shows: Low number of Active Tasks Many tasks complete in milliseconds Fewer tasks than available CPUs Which approach should be used to adjust the partitioning for optimal resource allocation?
Answer options
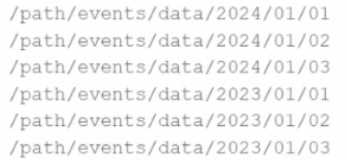
A data engineer is asked to build an ingestion pipeline for a set of Parquet files delivered by an upstream team on a nightly basis. The data is stored in a directory structure with a base path of "/path/events/data". The upstream team drops daily data into the underlying subdirectories following the convention year/month/day. A few examples of the directory structure are: Databricks DATABRICKS CERTIFIED ASSOCIATE DEVELOPER FOR APACHE SPARK 3 question Which of the following code snippets will read all the data within the directory structure?
Answer options
A data engineer is building a Structured Streaming pipeline and wants the pipeline to recover from failures or intentional shutdowns by continuing where the pipeline left off. How can this be achieved?
Answer options
Question 1 of 10

Source context

How this practice set is maintained

Maintained by the CertMage content team, this page loads questions from the exam dataset connected to its preparation resource. When an answer includes a supporting reference, it is shown with that answer so you can review the underlying vendor documentation.

Certification objectives, interfaces, and vendor services can change. Verify important details against the provider's current exam guide and documentation before your exam.

Scroll to Top